Exploring the Strong Link Between Muscle Hypertrophy and Strength Development
Published Jun 11, 2026Reads 790By Greg Nuckols
Recent research reveals that hypertrophy significantly predicts strength gains, challenging previous findings that downplayed this relationship in untrained individuals.
## Unpacking the Relationship Between Hypertrophy and Strength Gains
Understanding the intricate dynamics between muscle growth (hypertrophy) and strength gains isn't just a niche query—it's a fundamental aspect of exercise science that affects training protocols everywhere. This piece hinges on recent research by Marques and colleagues, which promises to shake up what many thought they knew about this connection. It’s not merely a rehash of past findings; it positions itself as a critique of conventional statistical methodologies that may have obscured our understanding.
For those who may not be well-versed in the literature, here’s a quick primer. Previous studies generally indicated that the connection between hypertrophy and strength in untrained individuals was quite weak. However, sophisticated data suggested that this bond strengthens as one's training maturity grows. Simply put, novices may see minor size increases with even greater upswing in strength, assigning early gains largely to technique rather than muscle mass. In contrast, seasoned lifters experience a closer correlation where muscle size increasingly predicts strength.
Yet Marques' recent work challenges this perception, positing that earlier studies may have underestimated the hypertrophy-strength relationship. The crux? A shift in statistical analysis. Historically, researchers relied heavily on between-participant methods—essentially comparing groups rather than tracking change within individuals. This might lead to misleading conclusions, suggesting less correlation where, actually, a strong relationship could exist when examined within subjects.
To visualize this, consider two individuals starting with the same muscle size but differing inherently in factors like muscle attachment points. Even if they both gain the same percentage in muscle size, their strength increases could diverge—a detail that earlier methodological approaches could overlook. Marques' team advocates for a repeated-measures correlation approach, capturing nuanced intraindividual changes over time. This technique stands to provide a sharper lens on how muscle adaptations translate to strength improvements.
The traditional understanding dictated that attributes like moment arm mechanics or baseline muscle activation could skew the perception of hypertrophy’s influence on strength. The reality, as Marques indicates, is that by using a more refined statistical lens, researchers can reveal an entirely different picture—one where hypertrophy is a strong predictor of strength gains even within untrained subjects.
Marques and his fellow researchers focused on 39 untrained men who engaged in a 15-week resistance training regimen, specifically targeting the quadriceps. Tracking the results, they recorded significant improvements: an average increase of 21.6% in isometric knee extension strength and a robust 28.6% rise in knee extension one-rep max (1RM). Concurrently, quadriceps volume, assessed via MRI, grew by about 12.7%. It’s this comprehensive approach that offers fresh insight into how muscle growth can significantly contribute to strength, particularly with advancements in measurement techniques.
As you consider this topic in your own work or discussions, the implications are clear: if you’re still relying on outdated statistical methods, you could be missing critical insights. And for anyone dedicated to strength training, understanding this nuanced relationship may reshape how you approach your regimen moving forward.
The Implications of Statistical Methods on Correlation Values
The findings presented by Marques and colleagues are compelling at first glance, especially with their reported r-values of 0.89 to 0.92 for the correlations between hypertrophy and strength gains. However, the stark contrast with previous research raises important questions about the validity of these correlations. If taken at face value, one could argue that earlier studies completely overlooked a nearly perfect correlation because their statistical approaches were inadequate. Yet, can we accept that conclusion without further scrutiny?
Here's the kicker: when we juxtapose these results with the previous work from Vigotsky and his team, things become murky. If the only reason past research missed this strong correlation was because of using between-subjects methods, then Vigotsky's study—which also utilized a within-subjects method—should have revealed similar high correlations. Instead, it found that hypertrophy explained less than 25% of the variance in strength gains. This doesn't align with the notion that the methodology was the sole culprit for lower correlation values.
Interestingly, Marques employed a repeated measures correlation, a statistical method akin to a hierarchical linear model. This approach allows intercepts to vary while maintaining a constant slope across subjects. Vigotsky's model, however, went a step further, accommodating both varying intercepts and slopes. If hypertrophy genuinely accounts for more than 80% of variance in strength gains, the Vigotsky study should have recorded equally impressive findings—or even better, given its more nuanced statistical capabilities.
What’s truly perplexing is how we can reconcile these conflicting results. To get a clearer picture, consider this thought experiment: if hypertrophy and strength gains had zero connection, what would the correlation look like? Surprisingly, even in a hypothetical scenario where hypertrophy is irrelevant to strength gains, repeated measures correlations in Marques' study would still yield r-values around 0.81 to 0.83. This suggests that methods may produce inflated values under certain conditions, leading to the misleading impression that a substantive relationship exists where it does not.
Returning to the original findings, the reported r-values of .89 and .92 now seem inflated, raising skepticism about their real-world significance. In fact, upon careful examination, they imply merely a 12-17% increase in variance explained over what could be attributed solely to random chance, rather than genuine predictive power. To put it simply, while the correlations reported are undoubtedly higher than those from traditional methods, they do not inherently suggest a true, robust relationship.
Clarifying Misinterpretations
My take is that the lower values presented towards the end of Marques' tables offer a more honest representation of the study's outcomes. While there's certainly merit in acknowledging that standard between-subject correlations tend to downplay the strength of the relationship between hypertrophy and strength, the overreliance on repeated measures correlations also skews our understanding. The r = 0.89 correlation doesn't statistically differ from the null case; its confidence interval overlaps with r values you would expect if there was no relationship at all.
Repeated measures correlations inflate the perception of association strength, potentially misguiding researchers. This doesn't imply any wrongdoing on the part of the authors; rather, it's a misplaced focus on the statistical outcomes. They should have tempered their interpretations and remained cautious in presenting such high correlation figures.
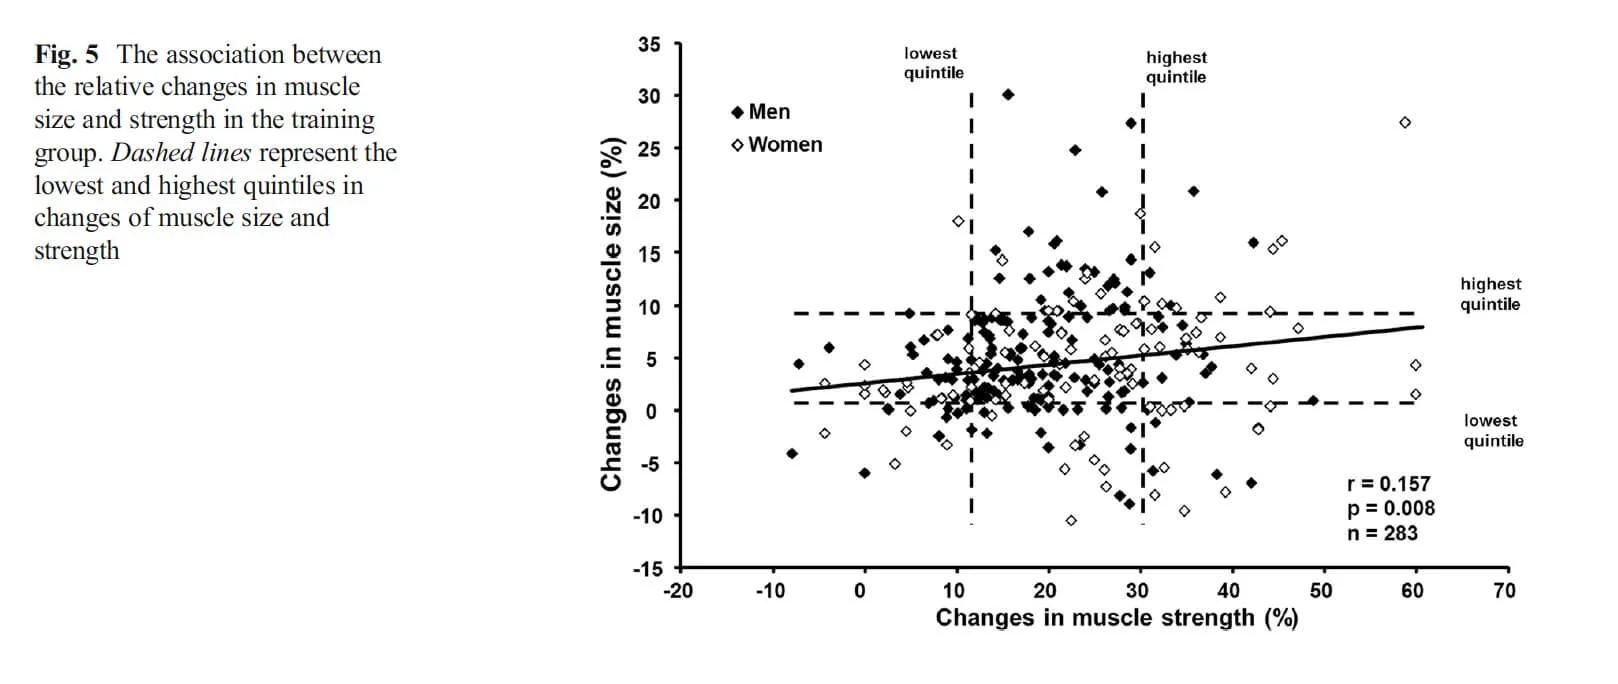
That said, even their conventional between-subjects analysis revealed stronger links than typically found among untrained lifters, with correlation values of 0.35 and 0.60 between hypertrophy and 1RM changes and isometric strength, respectively. This underscores an existing nuance: while the results deviate from the expected norm, they also highlight how statistical interpretations can significantly affect our understanding of muscle growth and strength relationships.
Ultimately, while the paper constructed a fresh perspective, the revelations of inflated correlations open up avenues for deeper inquiry. If you work in this domain, take these findings with a grain of caution. The implications of statistical methods used need to be thoroughly understood to avoid conclusions that might otherwise lead us astray in research and practical applications.
A Cautionary Note on Repeated Measures Correlation
Marques' recent study stands out for its extended duration—15 weeks—which is longer than the typical research timeline for untrained lifters. This additional time resulted in noteworthy hypertrophy and strength gains. Particularly interesting is how one of the strength metrics employed minimal skill, specifically the maximum isometric knee extension torque. This method effectively minimizes potential confounding variables related to different skill levels that can significantly skew strength adaptations. While the study's Pearson correlations surpassed the norm for untrained individuals, I’m not overly surprised. The researchers demonstrated a commendable level of methodological rigor.
However, here’s the thing: I think we need to be cautious about the increasing presence of repeated measures correlations in exercise science literature. My main objective was to explore the so-called “null case”—the correlations we expect when there’s actually no relationship. What I’ve uncovered suggests that these repeated measures correlations show limited sensitivity to mean change scores and subject variability at the outset. On the other hand, they’re quite reactive to changes in score standard deviations.
When evaluating strength and hypertrophy outcomes, it’s common to see coefficients of variation (CVs) around 1.0. This means that if the average strength increment in a study is 10 kg, the associated standard deviation will typically fall between 5 and 15 kg. As illustrated in [this figure](https://sportrxiv.org/index.php/server/preprint/view/214/707), repeated measures correlations ranging from 0.65 to 0.85 could signify minimal or even no real association, particularly when the CVs vary between 0.5 and 1.5.
Moreover, achieving a Pearson correlation lower than 0.5 isn't something that happens easily. Strengthening this correlation often necessitates either large outliers or a significant disconnect between predicted and actual changes. The repeated measures correlation will likely yield a substantial coefficient anytime two mean changes align directionally. For instance, even when two variables are moving independently, the correlation may misleadingly appear robust, as demonstrated in my quick plot from earlier.
Let’s be clear: I'm not dismissing repeated measures correlation as a useful tool. However, I foresee that interpreting these figures will require more effort than many researchers may anticipate. A surge in reported r-values between 0.7 and 0.9 may lead to misunderstandings—those seemingly high numbers don’t always imply a strong relationship. The nuances of these correlations warrant a more sophisticated interpretation.
If you're engaged in research involving repeated measures, I urge you to run simulations to ascertain the expected r and r² values for null scenarios within your dataset. Craft a dataset that embodies the descriptive statistics you expect to report, ensuring the outcomes are designed to be completely independent. By doing so, you’ll better grasp the true implications of your results, rather than simply leaning on the reported r-values.
For those consuming scientific literature, skepticism is equally warranted when encountering repeated measures correlations. Avoid accepting reported results at face value or interpreting them as conventional correlation coefficients. There’s a helpful [shiny app](https://lmarusich.shinyapps.io/shiny_rmcorr/) developed by the authors of the related paper that simplifies analysis significantly. It can serve as an invaluable resource, as it did for me during my examination of these correlations.
As I wrap things up, remember that understanding the underlying complexity of repeated measures correlations is vital. We must ensure we're not misled by their apparent simplicity or by the statistics they present. With that approach, we can draw more accurate insights from our findings.
Discussion
Sign in to join the discussion.